The Next AI Gold Rush: NVIDIA’s $5 Trillion Vision
NVIDIA’s AI story now spans devices people use directly and computers that help robots interpret the physical world. NVIDIA AI laptops humanoids are part of a wider platform connecting personal computing with machines that act in the world. A robot foundation model is an AI model trained on broad data to generalize skills across tasks and robot embodiments. That vision is broader than what is ready for everyday use.
The difference matters to buyers, developers, and companies weighing new AI systems. A laptop may run models locally, while a robot needs tools for training, testing, and safe action. Those are connected parts of physical AI, but they are not the same capability.
Readers can assess the technology more clearly by separating what runs on a laptop, what trains in simulation, and what must work safely on a robot.
NVIDIA AI Laptops Humanoids: What Is the On-Device Role?
A laptop can run AI locally when its GPU and shared memory fit the workload. That lets models and agents process data on the device, without sending every request to a remote service.
Local computing adds control, but model size and performance still depend on the exact system. NVIDIA’s planned RTX Spark laptops aim to bring large AI workloads onto portable computers.
RTX Spark brings large AI workloads onto a laptop
RTX Spark combines a Blackwell GPU with 6,144 CUDA cores and fifth-generation Tensor Cores. Those Tensor Cores support FP4 precision, a format used for AI calculations.
The system pairs that graphics processor with a 20-core NVIDIA Grace CPU. It offers up to 1 petaflop of AI performance and up to 128GB of unified memory.
Unified memory gives the CPU and GPU access to one shared pool. That design can help fit large models and their working data inside the laptop.
NVIDIA says RTX Spark can run large language models with up to 120 billion parameters and up to 1 million tokens of context. A token is a piece of text that a model processes.
RTX Spark laptops are planned for fall 2026 from ASUS, Dell, HP, Lenovo, Microsoft Surface, and MSI. Acer and GIGABYTE models are expected to follow.
The fall 2026 window is a planned release, not proof that every model or configuration is already for sale. Buyers should distinguish announced systems from products they can actually order.
Local agents extend the laptop beyond chat
Local AI agents can handle steps in a task, rather than only answer a prompt. They may work with files, apps, or creative software on the laptop.
Keeping model work on the device can limit how much data leaves it. The actual privacy benefit depends on the apps, settings, and services involved.
RTX Spark laptops are designed for on-device agents, with Windows security features and NVIDIA OpenShell for agent control. These controls help manage what an agent can do.
Agents still need clear limits. A system that can open files or run software should have permissions matched to its job.
Check the exact model and configuration before assuming an announced laptop supports a particular local workload.
How Does NVIDIA’s Robotics Stack Train and Run Robot Models?
A robot model needs large-scale training and a way to test movements before controlling hardware. NVIDIA’s robotics stack splits that work across model training, simulation, and onboard inference.
A robot foundation model must still be tested on the robot and in its real operating conditions. Simulation helps, but it cannot erase a mismatch in data or hardware.
GR00T builds general skills from multimodal data
Isaac GR00T is an open reference platform for humanoid robot models. Its models use language and images to connect instructions with actions.
They can learn from captured movement, synthetic data, and internet-scale video. Robot learning can include imitation, where a model learns from demonstrations, and other training methods.
The aim is to adapt skills across different robot embodiments. A model could learn to pick up an object, place it somewhere, or complete several steps in order.
Such tasks demand more than recognizing words or images. The robot must map a request to movements its body can safely perform.
Isaac Sim and Isaac Lab make training repeatable
Isaac Sim and Isaac Lab serve different roles in simulation and robot learning. Isaac Sim models physical scenes, while Isaac Lab supports training and checking robot policies.
A policy is the set of rules a model uses to choose its next action. Developers can test those choices in repeatable environments before trying hardware.
DGX systems provide computing for model training. NVIDIA Omniverse supports simulation, while Cosmos tools can help create and test simulated environments.
A digital twin is a simulated replica of a facility or system. It can help developers study how a robot might act in a factory or warehouse.
Simulation training data must still match the target robot and the place where it will work. A policy trained on a smooth floor may fail on a cluttered or uneven one.
Jetson Thor runs models on the robot
After training, a robot needs an onboard computer to process sensor data and run models. Jetson Thor modules offer up to 2,070 FP4 TFLOPS of AI compute and 128GB of memory.
They operate from 40 to 130 watts. NVIDIA reports 7.5 times the performance and 3.5 times the energy efficiency of AGX Orin.
The Jetson AGX Thor Developer Kit has a 14-core Arm Neoverse-V3AE CPU and 128GB of 256-bit LPDDR5X memory. Its memory bandwidth is 273GB per second.
The Jetson T5000 delivers 2,070 FP4 TFLOPS and 128GB of memory, using 40 to 130 watts. The T4000 delivers 1,200 FP4 TFLOPS and 64GB, using 40 to 70 watts.
Camera capacity also differs by setup. The developer kit supports up to 20 cameras through Holoscan Sensor Bridge, while the T5000 supports up to six through 16 MIPI CSI-2 lanes.
Match the onboard compute and camera inputs to the robot’s actual sensor setup before settling on a deployment design.
Where Can Humanoid Robots Work, and What Limits Them?
A humanoid’s practical advantage is its human-shaped form, which can make existing workspaces usable without redesigning them around another robot. That is a potential benefit, not proof that humanoids can handle every human task.
Many humanoid robot use cases remain in early research and development. Their ability to work near people depends on the task, the setting, and careful testing.
Possible use-case areas include:
- Manufacturing, such as moving parts between work areas.
- Warehouse and logistics work, including moving goods.
- Healthcare support tasks in care settings.
- Home assistance with selected household tasks.
- Customer service in public or commercial spaces.
Humanoid development uses machine learning, imitation learning, and reinforcement learning. These methods do not remove limits in sensors, motors, balance, or hand control.
A robot also needs enough onboard compute to interpret sensors and respond. Battery energy, training data, and the range of tasks it has practiced affect performance.
Safety includes more than avoiding a collision. Functional safety covers hazards in the machine, robotics safety covers movement, and collaborative safety concerns work near people.
Sensor safety and AI safety also matter. IEC 61508, ISO 13849, and ANSI/RIA R15.606 are safety frameworks; ISO/IEC TS 22440 is an emerging AI-safety standard.
Human collaboration should be validated as a safety requirement, not assumed from a human-like shape.
What Does an NVIDIA-Powered Humanoid Look Like in Practice?
Agile ONE SN makes the demands of a general-purpose humanoid tangible through its compact body, articulated hands, and onboard AI computer. Its design gives developers a concrete platform to study, but its scheduled availability is still in the future.
Agile ONE SN is scheduled to be available in early 2027, which does not show that it is already operating at scale. Product plans and broad deployment are different milestones.
Agile ONE SN combines human-scale movement with onboard compute
The robot is 1.40 meters tall and weighs 40 kilograms. It has 31 degrees of freedom, meaning its body can move through many controlled joints.
Each arm can carry a 3-kilogram payload. Two five-finger WUJI Hand 2 hands give it 20 degrees of freedom per hand.
Its NVIDIA Jetson Thor onboard computer provides 2,070 FP4 teraflops of compute and 128GB of unified memory. That computer must run AI tasks within the robot’s power and heat limits.
Head and wrist cameras capture views from different angles. Lidar sensors measure distance, while inertial measurement units track motion and orientation.
The combination gives developers several types of sensor data to work with. It also raises practical questions about camera placement, data flow, and how quickly the robot can react.
Simulation assets and physics tools expand testing
Isaac Lab 3.0 is generally available with multi-GPU workflows. It includes the Newton and NVIDIA PhysX physics engines for testing robot motion.
Using more than one GPU can support larger or more demanding simulation work. Physics engines help model contact, motion, and forces in virtual environments.
SimReady Central Library contains more than 2,000 simulation-ready robotics and factory assets. Developers can use those assets to build test scenes instead of creating every object from scratch.
A useful simulation still depends on how closely its objects and physics match the intended task. A hand gripping a virtual tool may behave differently from one holding the real tool.
Compare a robot’s payload and hand dexterity with the task it must perform, not just with its human-like appearance.
How Do Developers Move From Simulation to Real-World Deployment?
Start with a specific robot task and the hardware that will perform it, then choose training and simulation tools around those limits. That keeps development focused on what the robot must actually do.
Success in simulation does not replace testing a policy on its target hardware and sensors. Physical robots encounter conditions that virtual scenes may not capture.
Set up the training and simulation workflow
NVIDIA Isaac is an open robotics development platform. It includes simulation and robot-learning frameworks, CUDA-accelerated libraries, AI models, and reference workflows.
A practical workflow has three steps:
- Define the robot and task, then gather data that fits its body, sensors, and work setting.
- Train and evaluate policies in Isaac Sim and Isaac Lab, using reinforcement or imitation learning where suitable.
- Deploy to Jetson hardware and validate the policy with the robot’s real sensors.
DGX systems can support demanding model training. Isaac Sim creates simulated scenes, while Isaac Lab helps train and assess robot policies in those scenes.
NVIDIA Omniverse supports simulation workflows and digital twins. A digital twin can represent a facility or work area, giving developers a place to test robot behavior.
Reinforcement learning can train a policy through rewards and repeated attempts. Imitation learning can use demonstrations, which may suit tasks with clear examples.
Validate the robot policy on its target hardware
Once a policy is ready, developers can run it at the edge, meaning on a computer carried by the robot. Jetson Thor is based on Blackwell architecture and includes a functional safety processor, a high-performance CPU cluster, and 100Gb Ethernet bandwidth.
Those features support onboard computing and data movement, but they do not certify the full robot. Testing must cover the actual sensors, software, and physical task.
Isaac ROS connects NVIDIA’s robotics tools with ROS 2, a common robotics software framework. That link can help developers work with existing robot software.
During trials, record cases where the physical robot acts differently from its simulated version. Then repeat those cases after changing the policy.
Keep a record of failures that appear only on physical hardware so that policy changes can be retested against them.
Which Companies Are Building on NVIDIA’s Robotics Platform?
A real-time robot stack has to move sensor data into perception and control without adding needless processing delays. Companies are building systems around NVIDIA tools to address that need.
A platform integration does not prove certification or safe performance in every deployment. It shows that named tools are part of a company’s work, not that every robot is finished.
Humanoid is integrating a real-time edge runtime
On October 21, 2026, Humanoid described integrating Jetson Thor, Isaac OS, Holoscan Sensor Bridge, and Holoscan SDK into its next-generation robot platform.
The company consolidated two onboard computers into one Jetson Thor system. It also uses GPU-accessible camera data to reduce data copies and CPU workload.
Isaac OS provides a GPU-native runtime, which lets software use the graphics processor for tasks. Multi-Gigabit Ethernet supports up to 100Gb of bandwidth for sensor and control data.
That design aims to move camera information through the system with fewer steps. The result depends on how the full robot handles sensing, processing, and control.
European companies are building on the open platform
NVIDIA named ABB Robotics, Flexion, Hexagon Robotics, Humanoid, KUKA, NEURA Robotics, Sereact, and Universal Robots among European companies building on its open robotics platform.
These names show a broad mix of robotics firms and industrial automation groups. A shared platform can give developers common tools, while each company still builds its own systems.
Robot-learning and safety collaborations widen the ecosystem
NVIDIA named 1X, Agile Robots, Humanoid, Maven Robotics, Mentee, MicroAGI, Rhoda, Sereact, and Skild AI as supporters of open-source robot-learning reference workflows on DGX Station.
Open workflows can give developers a shared starting point for training and testing. They do not ensure that a policy will transfer well to every robot.
Agile Robots, Agility, Dexory, FORT Robotics, and KION are integrating NVIDIA Halos into robotics safety architectures. The work adds safety tools to their systems, but does not establish safe performance in every setting.
Check what a partner has actually integrated before treating a platform relationship as evidence of a finished robot capability.
What Do NVIDIA’s Financial Results Reveal About Its AI Business?
NVIDIA’s fiscal Q2 2027 results show how heavily its business is tied to accelerated computing and Data Center demand. Revenue for the quarter ended July 26, 2026, reached $96.2 billion.
That total was up 106% from a year earlier, while Data Center revenue rose 117%. The figures show strong growth, but each business line has a different role.
Data Center revenue was $89.0 billion in the quarter. Edge Computing revenue was $7.2 billion, up 27% year over year.
The two figures describe separate parts of the business. Data Center revenue was much larger, while Edge Computing grew at a different rate.
NVIDIA reported a gross margin of 75.0% under both GAAP and non-GAAP accounting. Gross margin is revenue left after the cost of goods sold, before other expenses.
Reported results describe a completed quarter. NVIDIA’s fiscal Q3 2027 revenue outlook is a forecast of $108.0 billion, plus or minus 2%.
The forecast assumes no Data Center compute revenue from China. That condition matters because a forecast depends on the assumptions used to set it.
Market value is another measure, but it is not operating revenue. Nasdaq reported NVIDIA’s market capitalization at $5.252 trillion on October 27, 2026.
Market capitalization reflects share price and shares outstanding at a point in time. It can change as investors trade the stock.
Read the Q3 outlook as conditional guidance, especially because its stated assumption excludes Data Center compute revenue from China.
Which NVIDIA Laptop Examples Fit Different AI and Gaming Needs?
Laptop choice starts with the workload: demanding games and creative projects call for a different balance of GPU, display, and portability than everyday use. The best fit depends on the exact configuration, not just its name.
Match the processor, graphics chip, screen, and weight to the apps you plan to run. NVIDIA’s 2026 gaming-laptop guide describes RTX 50-series Blackwell mobile GPUs as its latest laptop graphics generation.
These four examples show different hardware choices:
- Razer Blade 18 (2026): Intel Core Ultra 9 290HX Plus and NVIDIA GeForce RTX 5090 Laptop GPU.
- MSI Katana 15 HX: Intel Core i7-14650HX and NVIDIA GeForce RTX 5050 Laptop GPU.
- Acer Predator Triton 14 AI: Intel Core Ultra 288V and NVIDIA GeForce RTX 5070 in a 3.5-pound laptop.
- Asus TUF Gaming A14: a 14-inch gaming laptop based on AMD and NVIDIA hardware.
The Razer’s 18-inch display has two modes. It can show 3840 by 2400 pixels at 240Hz or 1920 by 1200 pixels at 440Hz.
The higher-resolution mode gives more detail, while the faster mode favors a higher refresh rate. Those settings suit different gaming and creative priorities.
The MSI has a 15.6-inch, 1920 by 1080 display with a 144Hz refresh rate. Its parts offer a different mix from the Razer, without making it a winner for every buyer.
The Acer combines a high-end mobile graphics chip with a 3.5-pound body. That weight may matter to someone who carries a laptop often.
The Asus is a smaller 14-inch option with AMD and NVIDIA hardware. Its exact parts depend on the configuration, so its name alone does not define performance.
Gaming laptops can also support creative software and some local AI tasks. The fit depends on the software, memory, graphics chip, and cooling in each model.
Compare the exact GPU, screen, and weight of the configuration you can buy rather than relying on the product family name.
Conclusion
NVIDIA’s expanding AI opportunity is clearest when its computing platforms are viewed as tools for specific workloads, not as a promise that every use case is already solved. Local computing and robot models connect, but useful physical AI still depends on testing, hardware fit, and safety.
Developers can start with one robot task and identify the data and tools needed to test it. That keeps model development tied to a clear result instead of a broad claim about what robots might do.
To get started, select one robot task and map the data, simulation, and onboard hardware needed to test it safely.
The Sky Is the New Highway: Tesla, Flying Cars, and the Future of Mobility
A car that briefly leaves the ground can make flying cars feel close; routine air travel requires much more. Safe, regular trips need vehicles that work in two demanding settings. They must handle public roads, then meet the needs of controlled aircraft flight.
That gap matters to people weighing new ways to travel around cities, where traffic can make ordinary commutes slow. A dramatic clip may show lift, but it cannot show every limit that shapes daily use.
This report separates flight tests from usable transportation. It looks at designs, buying plans, rules, and the systems needed to make air travel routine. A demonstration alone cannot establish safe, legal daily use.
The useful question is not only whether a vehicle can fly, but what it can legally and reliably do.
What the Rise of Flying Cars Looks Like in 2026
Flying cars are becoming a real engineering effort, but designs range from roadable aircraft to eVTOLs. Those are different machines, and neither makes routine air travel a reality yet.
Prototypes can fly, but everyday access has no dependable timeline. A roadable aircraft is a vehicle designed for both public-road use and aircraft flight. Some designs transform between driving and flight, while eVTOLs are built for vertical takeoff and landing.
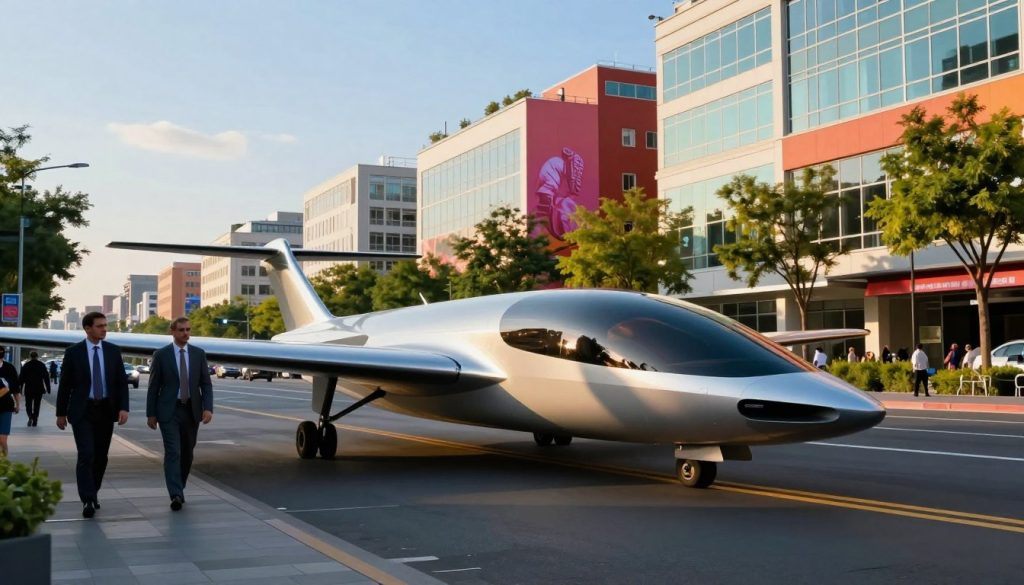
Roadable aircraft and eVTOLs serve different purposes
Roadable aircraft aim to combine the roles of cars and aircraft in one vehicle. Some fold or shift parts for flight, then return to a road-going form. An eVTOL instead takes off vertically, like a helicopter, and does not need to become a road vehicle.
The idea has older roots than today’s technology. The Autogiro Company of America AC-35 first flew on March 26, 1936, then changed to road configuration on October 26. Six Taylor Aerocars were built after the first successful flight in 1949.
Klein Vision’s AirCar completed a 35-minute flight in June 2021. It received aircraft type certification in January 2022. That aircraft approval did not, by itself, grant permission for public-road use.
Why a flying prototype is not a mass-market vehicle
A flying car needs more than working engines and wings. Its design must meet aircraft needs in the air and road rules on the ground. The word “flying” can describe a test, not a complete travel service.
Mass use also depends on safe operation, support systems, and approval for the vehicle’s intended uses. Those steps differ by design and location. A prototype’s ability to fly is only one milestone; road use, aircraft approval, and practical operation are separate tests.
What Did Tesla’s Flying Car Demo Actually Prove?
Tesla’s October 2026 demonstration was real, but it showed a remotely controlled Roadster making a brief aerial maneuver. It was not sustained flight or proof of aircraft operation.
The clip establishes a short lift and landing, not range or controlled forward travel. The Elon Musk flying car video shows a prototype, not a Roadster that people can operate as an aircraft.
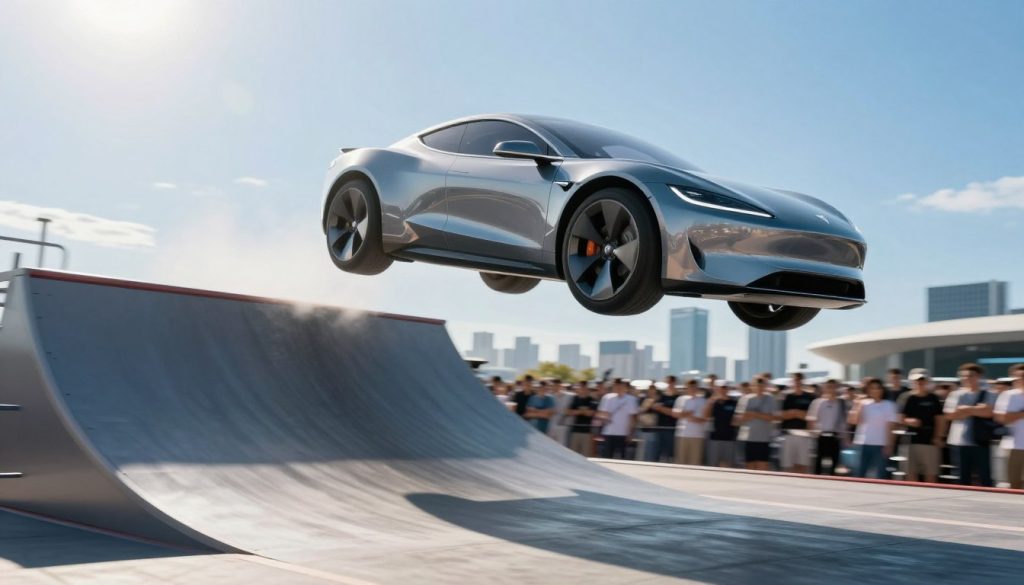
The remotely controlled Roadster demonstration
The car drove up a curved ramp, flipped with thrusters, and landed. Tesla said SpaceX designed the thrusters, and the company described rolls and other aerial maneuvers.
The demonstration used 10 nozzles. Musk said remote control helped avoid harming anyone. Tesla’s thrusters also differ from Alef’s distributed electric propulsion, which uses multiple propellers around the vehicle.
The Tesla flying car is real as a remotely controlled prototype, but the clip does not show an aircraft-ready car. The Tesla flying car video is real footage of a brief maneuver.
A brief hop is not sustained aircraft flight
The footage does not show a sustained flight path, a useful travel range, or controlled forward flight. A flip can make a striking clip, but it does not answer how the vehicle handles ordinary aircraft operations.
Three checks help put flight demonstrations in context:
- Was the vehicle piloted, or was it remotely controlled?
- Did it sustain flight beyond a brief rise and landing?
- Did it show controlled travel beyond a short lift?
The checks distinguish an aerial stunt from evidence of transport capability. A clip of a flip and landing cannot establish how far the vehicle can fly or how it performs in ordinary operation.
How Do the Alef Model A and Doroni H1-X Compare?
Alef’s Model A is designed to combine road use with vertical takeoff, while Doroni’s H1-X is a two-seat eVTOL still progressing through flight testing and certification. Their layouts differ, as do their current test stages.
A flight-test count shows testing activity, not customer readiness. Both vehicles remain at prototype stages, so planned use and listed performance are not the same as proven daily service.
Alef Model A: road fit and vertical takeoff design
The Alef flying car has room for two occupants and uses a body that forms its wings. Its cabin rotates during flight, while distributed electric propulsion supports vertical takeoff.
Alef says the Model A is designed to fit a regular driving lane, a parking space, and a standard-size garage. The company lists a 220-mile driving range and a 110-mile flight range.
Those are stated ranges, not a record of routine trips. The design also includes a full-vehicle ballistic parachute, intended to help protect occupants in an emergency.
Alef said it had logged its 1,000th flight in October 2026. That milestone indicates substantial prototype testing, but it does not show that buyers can use the vehicle for daily travel.
Doroni H1-X: testing and certification stage
Doroni’s H1-X is a two-seat personal eVTOL. The company reports more than 70 test flights, including manned flight testing in the United States.
The H1-X Special Airworthiness Certificate allows authorized manned testing. It is not production certification, which would address a different stage of approval.
Doroni targets completion of its certification flight campaign by late 2027. That goal marks a planned test milestone, not permission for broad customer operation.
A prototype’s test authorization should not be confused with approval for customer operation.
What Do Flying Cars Cost, and Can You Buy One?
The named flying-car projects range from refundable reservation deposits to an expected six-figure vehicle price. Those payments are not the same, and none means routine flight can begin.
A deposit reserves a place or version; it is not the full vehicle price or a guaranteed delivery. The Tesla flying car price people may encounter refers to planned Roadster versions, not a delivered aircraft.
Tesla Roadster prices and reservation deposits
Tesla said Roadster 2 production would begin in 2028, with a price above $200,000. It listed deposits of $50,000 for the Performance version and $250,000 for the Thrust version.
The Rocket version, which includes a full flight system, was invitation-only. A reservation does not mean the car is available now, and the listed deposits do not state the full cost of every version.
Early delivery targets and other reservation terms
Alef lists an expected Model A price of $299,999. Its pre-orders use a $150 deposit for the general queue or $1,500 for the priority queue.
Alef expected to deliver its first Model A vehicles to a limited number of early buyers by the end of 2026. Those vehicles were intended for controlled real-world testing, with production planned to ramp up in 2027.
Doroni offers H1-X reservations with a refundable $1,000 deposit. Its customer delivery target is 2028, and that goal depends on flight testing, FAA certification, and production.
These plans describe different stages, from a queue deposit to limited testing and a future delivery target. A vehicle price does not by itself show when ordinary buyers can use the aircraft or where they may fly.
Before paying a deposit, check whether it is refundable, what queue or version it covers, and what delivery stage the company is targeting.
What FAA Rules Apply to Flying Cars and Their Pilots?
A person cannot assume that a car with flight capability is legal to drive and fly without meeting road rules and the aircraft’s FAA requirements. Both approvals matter, and pilot rules depend on aircraft type.
A sport-pilot certificate is not blanket permission to fly every vehicle. Road use follows state and local road laws, while aircraft operation must meet federal aviation rules and the aircraft’s limits.
Pilot certificates depend on aircraft category
The Federal Aviation Administration, or FAA, sets pilot standards for different aircraft categories. Its Airman Certification Standards include powered-lift standards for private, commercial, instrument, airline-transport, and flight-instructor pilots.
Those powered-lift standards took effect on May 31, 2024. Separate practical test standards for powered-parachute and weight-shift-control sport pilots took effect on September 14, 2026.
Doroni says H1-X operators should hold a Sport Pilot Certificate or higher, subject to FAA rules. That plan does not set the rule for every aircraft or every pilot.
MOSAIC expands some light-sport aircraft options
The FAA’s MOSAIC phase II rules took effect July 24, 2026. They changed some light-sport aircraft limits, but the category still has detailed speed and operating rules.
For a light-sport-category airplane, maximum VS0 can be 61 KCAS. VS0 means stall speed in landing configuration. A sport pilot may fly an airplane only when its VS1 is 59 KCAS or less.
MOSAIC’s light-sport rules set no maximum takeoff weight for light-sport-category aircraft. Airplanes in the category may have up to four seats and a maximum VH of 250 KCAS.
Since October 22, 2025, sport pilots may operate qualifying aircraft with up to four seats and a VS1 of 59 KCAS or less, subject to requirements. Sport pilots may carry only one passenger.
No state offers a general public right to fly any car on public roads and in shared airspace. Check the aircraft category and its operating limits before treating a pilot certificate as permission to fly a particular vehicle.
What Still Stands Between Prototypes and Everyday Air Mobility?
Flying cars may be real prototypes today, but routine air mobility depends on linked problems in safety, airspace, infrastructure, and public acceptance. One working aircraft is not enough to make a dependable service.
No reliable date establishes whether flying cars will be routine by 2050. The NASA Urban Air Mobility Maturity Levels Scale ranks the complexity of aircraft, airspace, and support systems from level 1 to level 6.
Road vehicles and aircraft face different weight demands. A car needs parts for crashes and road use; an aircraft must stay light enough to fly safely.
Battery limits can restrict flight time and useful range. Vertical lift also takes power, and a vehicle must manage the hard shift from rising straight up to forward flight.
Weather can ground small aircraft, while noise may make frequent flights unwelcome. Cities also need safe landing sites, charging access, and clear plans for emergencies.
Unmanned Traffic Management, or UTM, is a digital way to coordinate aircraft movements. It could help manage busy routes, but airspace rules and public trust still shape how many flights communities accept.
Five practical needs must work together:
- Aircraft certification for the planned use
- Airspace management for safe shared routes
- Landing sites placed where trips need them
- Power supplies for charging and ground support
- Emergency procedures for aircraft and people below
These systems must fit the needs of passengers and people on the ground. A workable service must demonstrate safe operations for both, not just successful flight in a controlled test.
Conclusion
The most useful takeaway is to judge each vehicle by what it is approved and able to do now, not by a promise of future mobility. Flight capability, road use, customer access, and legal operation are separate milestones.
A reservation can mark interest, while a test flight can show that a prototype left the ground. Neither alone establishes that a buyer can use it for everyday travel.
Before relying on a purchase or reservation, check the vehicle’s aircraft approval, road status, and pilot requirements. Verify the vehicle’s current approvals and operating requirements before treating a reservation or demonstration as a path to everyday travel.
Self-Healing Software Is Here?! The Future of Tech Just Got Smarter
A service can recover automatically from a failure today, but Self-Healing Software Matrices do not mean it can reliably rewrite and validate its own code. Engineering teams already use automatic recovery to restore service and reduce development time lost to repeated incidents. Yet restoring service is different from repairing the defect that caused the outage.
For example, Kubernetes can restart failed containers and reschedule workloads. That action can bring an application back online, but it does not prove the application’s code is sound. Teams still need to investigate the cause and check that users and data remain safe.
MAPE-K is a model for managing a system by monitoring it, analyzing conditions, planning a response, executing that response, and retaining knowledge for future decisions. It can help teams organize recovery work, but it does not remove the need for human judgment. A change that could affect users or data needs careful oversight.
The useful question is not whether software can heal itself, but which failures it can safely handle.
What Are Self-Healing Software Matrices?
A system is self-healing when it detects a problem and initiates a recovery action, rather than stopping at an alert. In this article, Self-Healing Software Matrices means a coordinated approach, not a standard product category. A self-healing system acts on a fault and checks whether its response helped.
Monitoring identifies a condition, such as a rising error rate. Auto-remediation goes further by running a predefined response, such as restarting a failed process. Some recovery actions do not change source code at all.
That distinction matters because a network, application, or other software system may restore service without fixing its underlying logic. Kubernetes, for example, can restart failed containers and reschedule workloads. Those infrastructure actions can improve availability, even if the application bug remains.
A useful comparison is the immune system, which detects signs of trouble and triggers a response. Software can use signals and rules in a similar way, but it does not work exactly like an organism. A self-healing system follows its design, data, and limits; it does not necessarily learn from every event.
MAPE-K is one named architecture for organizing system self-management. Teams can use it to connect monitoring with analysis, planning, action, and retained knowledge. The value comes from coordinating those capabilities, not from applying a label to a single alert tool.
When comparing self-healing systems, ask what the software changes and what it checks afterward. A repair can target infrastructure, an application’s runtime behavior, test code, or production source code. Those choices have different risks and need different proof.
Ask whether a tool restores availability, changes code, or only repairs a test before judging its autonomy.
How Does the Self-Healing Loop Work?
A failed payment call with a rising error rate gives the system a signal, but not yet a safe fix. A self-healing loop turns that signal into a planned response, then checks the result. Recovery counts as successful only when a separate check confirms the expected service behavior.
MAPE-K names five parts of this process: Monitor, Analyze, Plan, Execute, and Knowledge. The Monitor gathers signals. Analyze looks for a cause, while Plan selects an allowed response.
Monitor and analyze system signals
Telemetry is the data a system produces about its behavior. Logs record events, metrics track values over time, and traces show how a request moves across services. Health checks add a simple view of whether a process responds.
Tools such as Prometheus and Datadog collect and display observability data. OpenTelemetry helps teams collect and share telemetry across systems. The tools can reveal a pattern, but engineers still need to decide what that pattern means.
A fixed alert threshold can catch a known condition, such as error rates passing a set limit. Anomaly detection can flag a change from the usual pattern, even when no fixed threshold has been crossed. Neither signal alone proves the root cause.
- Error rate: the share of requests that fail.
- Response latency: the time a request takes.
- Container health: whether a workload responds to its health check.
- Deployment version: the code version running during an incident.
Looking at these signals together can narrow the diagnosis. A rise in errors after a new deployment may point to a code change. A failing container with normal request data may point to a process or host problem.
Plan and execute a verified response
Plan chooses a response that fits the diagnosis and the system’s safety rules. Execute applies it, such as restarting a process or switching to a fallback. Knowledge stores useful facts, including past incidents and which responses worked.
A plausible fix is not the same as a verified recovery. Restarting a service may clear a temporary fault, but the same failure can return. A check should test a key user action, not just confirm that the process runs.
The loop also needs a limit. A system should stop or ask for help when signals conflict, an action fails, or the response could affect user data. That keeps automation from repeating a bad choice without review.
Keep the recovery check separate from the action, so a restarted service is not mistaken for a resolved incident.
Which Types of Self-Healing Software Are Used?
Four common types are infrastructure recovery, runtime self-repair, Automated Program Repair, and self-healing tests. Each addresses a different kind of failure. The main distinction is whether the response changes infrastructure, runtime behavior, application code, or test code.
A restart can restore availability without fixing the application defect. Teams should name what the action repairs, rather than treating every automatic response as the same kind of fix.
Infrastructure recovery and runtime fallbacks
Infrastructure self-healing restores a process or workload. Kubernetes can restart failed containers and reschedule workloads onto available resources. These actions can restore service, but repeated restarts may leave the original bug untouched.
Runtime self-repair uses prewritten behavior inside an application. Retry logic tries an operation again after a temporary error. A circuit breaker stops repeated calls to a failing dependency, which can prevent extra load.
A payment application can switch from a failed primary processor to a secondary processor. This fallback is useful when the alternate path is available and safe. It does not repair a processor’s code or explain why the first one failed.
Code repair and self-healing tests
Automated Program Repair (APR) means automatic source-code patch generation and repair. An APR tool proposes a patch and tests it against a defined task. Teams must still review whether the patch handles the real fault without creating a new one.
Self-healing tests change test code when a test can no longer find an interface element. A changed page locator may be replaced using other attributes or visual clues. This repairs the test script, not the application itself.
The four categories can work together, but their outcomes are not interchangeable. Infrastructure recovery aims to restore a workload. A runtime fallback keeps an application operating along a planned path.
Code repair changes the application’s source, while test repair changes how a check finds or uses an interface. Those changes need different reviews and success checks. A test that runs again may still miss a product failure.
Choose the category by what changes, not by how autonomous its alert or dashboard appears.
Where Does Self-Healing Software Show Up in Practice?
A practical example is a service that is restarted after a health check fails, while its application logic remains unchanged. Self-healing examples also include runtime fallbacks, repeatable QA setups, and business workflows that route exceptions. The recovery target determines what a team should verify.
A restored process does not prove that its application works correctly. Teams need checks that match the task, whether they restore a service, repair a test, or route a business issue.
Cloud and distributed services
Cloud systems can restart or reschedule an unhealthy workload after a failed health check. Kubernetes supports both actions in container-based services. They can restore availability, but the application may remain functionally broken if its underlying defect persists.
An application can also use a fallback when a dependency fails. A payment service might route a transaction through a secondary processor. Engineers should check that the alternate path protects the same user and data needs.
Business applications and operational workflows
Self-healing can support business processes as well as software and infrastructure. A workflow can detect an exception, send it to a human expert, then retain the expert’s resolution for future decisions. The process does not need to make every decision on its own.
That pattern can help with repeat issues that have clear signals but need human judgment. For example, a work queue can flag a failed step and route it to the right group. A person can resolve the case and record what worked.
Development pipelines and test environments
QA environments benefit when teams can provision them in a repeatable way. Terraform and Chef help automate infrastructure provisioning. Infrastructure as code records setup rules so teams can recreate an environment with less manual variation.
A development pipeline may rebuild a test environment after a failure. That is a useful recovery, but it is not the same as fixing an application defect. A repaired test script also does not show that production behavior is correct.
Teams should keep the checks separate. Confirm that the environment came back, then run the tests that cover the application’s expected behavior. This can expose a broken feature that a simple health check would miss.
Treat an automatically restored test environment as a useful recovery, not evidence that the application passed its tests.
What Do the Code-Generation Results Actually Show?
In a 2025 evaluation, a proposed framework achieved 94.7% code correctness across 15,000 software engineering tasks in five domains. The study compared that result with 87.3% for its leading comparison approach. Those figures describe one evaluated model, not typical performance across production systems.
The test set also measured error detection, correction, and cross-architectural propagation. The system reached 95.2% sensitivity, with a 2.3% false-positive rate. It automatically corrected 94.7% of the errors it detected.
Cross-architectural propagation succeeded in 89.4% of reported cases. The framework reported a 54% reduction in critical errors and a 41% reduction in remaining development time. These results suggest that the method performed well on the tasks used in the evaluation.
Benchmark performance does not show that every codebase can accept a generated fix safely. Production software has its own dependencies, data, users, and failure patterns. A model may miss a condition that was not represented in its tasks.
Verification matters because a patch can solve one bug and introduce another. Teams should run relevant tests, review the code, and check the behavior around the fault. Human review remains important when a change could affect users or data.
The results give engineering teams a way to discuss the promise and limits of code repair. They do not replace a review of the actual patch, its test coverage, or its effect on the application. Those checks shape whether an automatic change is acceptable.
Read these results as evidence about that evaluated framework, not as a guarantee for every codebase or repair task.
How Do Self-Healing Test Systems Repair Broken Tests?
A UI test can fail because a button moved in the page structure, even when the feature still works. A self-healing test tool can find the control through other attributes or visual information. That repair helps only when the interface changed without changing its intended behavior.
A healed selector must still target the control the test was meant to use. A test can fail because of a real regression, so blindly updating its locator can hide a product defect.
Locator repair when interfaces change
A locator tells a test where to find an item on a page. It may use a label, a name, a page structure, or another attribute. When designers change the interface, the original locator may stop matching.
A self-healing tool can compare other signals and suggest a new selector. That can save QA teams from fixing test code after harmless page changes. It can also choose the wrong button if several controls look alike.
QA teams may spend up to 60-70% of their effort fixing tests rather than increasing test coverage in the 2025-26 context discussed. That makes test repair appealing, but speed alone is not proof of a valid test.
QA checks that separate a healed test from a real bug
Teams should check why the test failed before accepting a new locator. If the feature changed by design, the test may need an update. If the feature broke, changing the test could hide the regression.
Monitoring signals can act like sensors in a nature-based comparison, while repair agents act on diagnosed problems. The comparison helps explain the roles, but software follows programmed rules and model choices. It does not heal through biology.
Examples of tools or platforms with self-healing capabilities include:
- Healenium
- Testim.io, described as AI-driven UI testing
- Mabl, which supports continuous testing
- Katalon Studio
- Functionize, an AI-powered autonomous testing platform
The list shows examples, not a ranking of quality. A team should judge a tool by whether it preserves the test’s purpose and exposes its changes for review. Independent checks can catch a repair that only makes the test green.
Require a human or independent check to confirm that a repaired locator still targets the intended control.
What Can Self-Healing Networks and Infrastructure Deliver?
Self-healing network tools focus on maintaining or restoring connectivity and managing traffic when network conditions change. They can respond to an infrastructure fault by shifting traffic or restoring a network path. The expected benefit is less disruption, not guaranteed uptime.
The self-healing networks market was valued at $960.0 million in 2024. It is projected to reach $1,550.7 million in 2026 and $5,075.9 million in 2030, with a 33.2% projected compound annual growth rate from 2025 to 2030.
In 2024, North America accounted for 38.0% of global market revenue. Solutions made up over 60.0% of the market by offering. Hybrid networks accounted for over 47.0% by network type.
Cloud deployment held over 63.0% by deployment type in 2024. Network traffic management accounted for over 22.0% by application. Self-healing network services are projected to grow at a 33.9% annual rate from 2025 through 2030.
Cisco ThousandEyes, Juniper Apstra, and IBM AIOps are examples of tools in this area. A report says AI-driven tools such as these can reduce downtime by up to 70%. That figure is a reported upper limit, not a result every network should expect.
Network automation can help teams respond to faults faster, but the outcome depends on the failure and response. Teams should measure their own service availability and time to restore service. A market projection does not show what one network will achieve.
Treat a market forecast as a measure of projected market growth, not a promise of a specific network’s uptime.
What Can Go Wrong When Software Heals Itself?
An automated fix can worsen an incident when the system mistakes a temporary signal for a real fault. False positives may trigger needless changes, while endless restart or retry loops can add load. Automation needs limits before it takes action.
High-impact repairs need review or approval until teams have tested their effects under realistic failure conditions. A narrow, reversible action is a better fit for automatic execution than a production code change.
A restart loop can hide the root problem while repeatedly interrupting service. A circuit breaker can stop repeated calls to a failing dependency. Bounded retries also prevent an application from trying the same failed action without end.
Test automation brings a different risk. A tool may change a test after a real application regression, making the test pass while the feature stays broken. QA teams should check the behavior, not just the updated test result.
An unsafe rollback can lose data or disrupt users if it reverses changes that other work depends on. A rollback should have a clear scope and a way to check its effect. A canary deployment can limit exposure by testing a change with a small share of traffic.
Automated patching can also create a security exposure. A patch may change access controls or add unsafe behavior. Model validation and audit trails help teams see what the system changed, why it changed it, and who approved the action.
Ownership needs to be clear when an AI-generated change causes harm. Teams should know who reviews the patch, who approves deployment, and who responds if it fails. Human intervention remains part of safe operations.
Keep high-impact repairs behind a review or approval gate until their behavior has been tested under realistic failure conditions.
How Should Teams Start Using Self-Healing Automation?
Start with one recurring failure that has a clear, reversible response, rather than automating every alert. A narrow first step lets teams learn whether the signal and recovery action work. Do not begin with an action that can change production code or user data without review.
Build the basics first: infrastructure as code, automated tests, logging, monitoring, alerting, and rollback. Terraform and Chef can help teams provision infrastructure in a repeatable way. Runbooks explain what responders should check and do.
Use this short phased checklist:
- Identify one recurring failure and its detection signal.
- Define a bounded response with a clear stop condition.
- Test recovery and rollback in a safe environment.
- Review the results with the responsible team.
Encode deterministic recovery before introducing AI-generated changes. A fixed rule is easier to test and explain. Teams can add more autonomy only after they understand the action’s effects.
Business-process recovery can diagnose an exception, route it to a human expert, and learn from the expert’s resolution. This keeps human judgment in the process while helping teams handle recurring cases.
Keep the first automated action narrow enough that the team can verify its outcome and reverse it.
Conclusion
Self-healing is most useful when its limits are as clearly designed as its corrective actions. Bounded infrastructure, runtime, and test tasks already benefit from automatic recovery. Trustworthy autonomous code repair still depends on verification and human review for high-impact changes.
One recurring failure mode gives an engineering team a practical place to start. Document the signal that detects it, the reversible response, and the check that proves recovery. That record helps the team judge whether automation worked before expanding its reach.
Choose one recurring incident, define a reversible response and verify the result before expanding automation.
The New Tech Talent Playbook: AI Skills Are the New Must-Have
A weekly sales report once took hours of sorting and checking; AI can now draft a summary in minutes. The Shift in Talent Demand Towards AI reaches beyond software teams, changing what employers expect from professionals in many fields. AI literacy is the ability to use AI tools critically, understand their limits, and apply them responsibly to work.
For someone weighing a career change or looking for a new job, the change can feel both practical and uncertain. AI does not make work a simple choice between technology and people. It changes how tasks get done and where human judgment matters most.
This article explains the forces behind new hiring needs, the roles and skills taking shape, and how employers assess candidates. It also offers practical ways to build and show useful ability. What is driving employers to seek AI capabilities now?
Why Is the Shift in Talent Demand Towards AI Accelerating?
A company that once tested a chatbot with a small group may now connect it to customer support. Moving from a trial to daily operations calls for practical expertise in data, systems, and oversight. Employers need people who can build, connect, and improve AI systems used in real work.
This shift is not the same as every job growing. McKinsey’s July 2025 analysis found that postings fell fastest in roles most exposed to AI. That finding concerns job postings, not proof that whole occupations have vanished.
AI is moving from experiments into everyday operations
Many organizations now aim to place AI inside existing products and work steps. Companies need talent to prepare data, connect platforms, test results, and keep systems useful as needs change. The work can span software development, customer service, finance, and operations.
Established employers and AI-focused businesses are building specialist teams to support these efforts. That does not mean workers are fleeing specific firms. It means more companies are giving AI work a defined place in their strategy and teams.
Skills gaps raise the value of practical expertise
In a UK government AI Labour Market Survey 2025 report, published in January 2026, 97% of businesses reported at least one AI-related skills gap. That figure describes businesses in the United Kingdom, not the United States. It points to a gap between plans and the skills available to carry them out.
For candidates, shown ability may improve their leverage in the market, though results depend on the role and employer. Companies still need people who can build dependable systems and fit them into real work. Those needs help explain the specific roles organizations are adding.
What AI Roles Are Organizations Adding?
A company building a customer-facing AI feature also needs dependable model infrastructure behind it. Useful products rely on engineers who can keep systems working and teams who can connect them to customer needs. AI roles often fall into two groups: building systems and applying them to products or workflows.
Infrastructure work includes scalable data pipelines and cloud environments used to deploy models. Some newer specialties focus on how AI systems handle information and work steps. The titles can sound alike, but their tasks differ.
Roles that build and maintain AI systems
AI and machine learning engineers develop models and the software around them. Data engineers build pipelines that gather, move, and prepare data. AI infrastructure engineers create scalable data pipelines and cloud environments for deploying models.
Context engineers structure information and workflows so AI tools receive useful inputs and produce more relevant outputs. Memory engineers design ways for systems to retain and use information over time. These roles help teams manage the foundations behind AI products.
Roles that bring AI into products and workflows
Other professionals connect technical systems to customer experiences and business needs. Common examples include:
- AI and machine learning engineers build and maintain models.
- Data engineers prepare and manage data pipelines.
- AI product managers guide product goals and development.
- AI integration specialists connect tools with existing platforms.
- Context and memory engineers shape how systems use information over time.
AI product managers help teams decide what a feature should do and how to measure its value. Integration specialists make tools work with current business systems. Titles vary by employer, and one broader role may combine several duties.
Some teams may assign context or memory work to engineers rather than hire for separate titles. The task matters more than the label. Employers still expect people in these roles to show the capabilities that make systems reliable and useful.
Which Skills Make Candidates Valuable?
An AI feature can run without errors and still fail if it gives customers advice they cannot use. Technical skill alone does not make a solution fit the problem. Valuable candidates pair the right technical skills with clear judgment about business needs.
The expertise a role needs depends on its work. Some jobs focus on data foundations and pipelines; others rely on cloud systems, model basics, or integration. Candidates do not need every tool or skill for every role.
Technical skills for building and integrating AI
AI and machine learning fundamentals help professionals understand how models learn and where they can fail. Data engineering and pipelines matter when systems need well-prepared information. Cloud platforms such as AWS, Azure, and GCP support many ways to run and manage these systems.
APIs, integrations, and automation help connect AI tools with other software. A developer linking a model to a sales platform, for example, must consider how data moves between systems. Prompt engineering, or writing clear instructions for AI tools, is useful across roles.
Prompt engineering is best treated as a practical skill, not a guaranteed standalone job title. Technical requirements follow the task: building a model differs from adding an existing tool to a workflow. That distinction helps professionals focus their learning.
Human and commercial skills for applying AI
Problem-solving helps teams spot when a tool misses the real issue. Communication lets technical and nontechnical people agree on what a feature should do. Adaptability matters because tools and work needs can change.
Commercial awareness connects technical choices to cost, customer needs, and business goals. A team might build an accurate model, yet still need to ask whether it makes a process better. These capabilities help turn technical work into useful outcomes.
Once the needed skills are clear, employers must decide how to judge them. A résumé alone may not show how a candidate handles the work.
How Are Employers Changing AI Hiring?
A hiring team may compare two applicants with different degrees and job histories, then find that both complete similar work samples. Skills-first hiring puts demonstrated ability ahead of degrees, past titles, or other traditional signals. Employers can use several kinds of evidence to judge whether candidates can do the work.
A coding challenge can test how someone handles a defined technical task. A realistic work sample may show how a candidate solves a problem closer to the daily job. Scenario-based tasks reveal how a person responds to choices with tradeoffs or incomplete information.
Portfolios let candidates show past projects and explain their part in each result. Verified credentials can confirm learning or a specific skill, though they may not show how someone applies it. These forms of evidence answer different questions.
Structured criteria can help hiring teams compare applicants in a more consistent way. For example, a team might score accuracy, safety, and clarity using the same guide. Structure can reduce uneven judgments, but it does not remove bias automatically.
Employers need to check whether their tasks and scoring rules favor some candidates without a job-related reason. A degree or credential may still matter when a role has a formal requirement. In other cases, work evidence can give capable professionals a way to show what they know.
How employers hire is only part of the change. AI also shifts daily tasks and the way teams share responsibility for their results.
What Changes in Everyday Work as AI Spreads?
A worker checks an AI-generated recommendation before it reaches a customer or shapes a business decision. Human review matters because AI can produce an answer that sounds sure but is wrong. Employees remain responsible for judgment, context, and the impact on customers.
AI applications include predictive analytics, automation, and intelligent systems that respond to data. They can sort routine information, draft text, or flag patterns for review. These tools can save time, but people still need to decide what the output means.
In finance, AI can help spot unusual transactions for an employee to check. In healthcare, it can sort records or support work with patient data. Marketing teams can use it to shape drafts, while manufacturers may use it to flag equipment issues.
Those examples show why AI literacy can matter beyond software jobs. A finance employee needs to question a flagged transaction, not accept every alert. A marketer still needs to judge whether a draft fits the brand and audience.
AI outputs can be confidently wrong, so review must match the risk of the task. Employees also need safeguards against exposing customer or company data in AI tools. A convenient prompt can create a serious privacy problem if it includes sensitive details.
When AI takes on some tasks, that does not prove an entire occupation will disappear. Jobs contain varied tasks, including work that needs care, judgment, and contact with people. As tasks change, ongoing learning helps employees respond, and professionals can take practical steps to build their skills.
How Can Professionals Stay Competitive?
A professional can use an AI tool to improve a real work process, then check the result before claiming skill. Applied practice helps professionals show what they can do, not just name tools. Build evidence through small projects with clear outcomes and careful checks.
A learning plan can begin with fundamentals, then move to practice that fits a person’s goals. Use realistic tasks rather than sample prompts with no link to real work. Keep track of the steps, checks, and results.
- Learn AI fundamentals, including common limits and safe use.
- Practice with tools on realistic tasks that match your work.
- Build a portfolio that shows the problem, your actions, and the outcome.
- Describe your contribution on a résumé instead of listing tools alone.
- Check output accuracy and data handling before sharing results.
A portfolio entry might show how an employee shortened a weekly report process while checking the summary against the original data. That example says more than a list of software names. It also gives an interviewer a clear way to ask about the work.
Keep ownership of résumé content. AI can help with wording, but candidates should check every claim and remove anything they cannot support. Unverified AI-generated details can damage trust during an interview.
Project-based or contract work can offer a way to gain applied experience. Access depends on a person’s time, finances, location, and current work duties. Personal or volunteer projects can provide other evidence when paid work is not an option.
Small, verifiable examples of learning can support a career move, even when they begin with one task. The central point is to pair useful AI ability with proof that it helps real work.
Conclusion
AI is changing which capabilities employers value, not just which tools they use. Professionals can strengthen their position by combining useful AI skills with judgment and results they can explain. That blend matters across roles as work and hiring change.
Choose one recurring work task and test an appropriate AI tool safely against a clear outcome. Check its accuracy, protect sensitive data, and keep a record of what improved. Then choose one practical learning action and build from its results.
AI vs. AI Commerce: The Future of Smarter Shopping
A shopper asking an AI commerce tool to find running shoes under $120 faces a choice between advice and action. One tool may suggest a few pairs, while another could buy one with permission.
That difference matters because AI can shape what you consider and how quickly you decide. It can also take on more steps, depending on the task and the access you allow.
Neither approach is right for every shopper or business. The useful question is where AI helps you make a decision and where you want it to act. First, the terms need a clear distinction.
What Is AI vs. AI Commerce?
A tool that suggests two suitable pairs of shoes supports your choice; a tool authorized to buy one can act for you. The difference is whether a person makes each decision or delegates a task.
AI commerce applies artificial intelligence to shopping or business tasks while a person remains the decision-maker. Generative commerce uses AI to create commerce content, product data, or shopping experiences.
Agentic commerce is commerce in which an AI agent researches options and carries out a purchase or other multi-step task on a person’s behalf, subject to the permissions that person gives it. These ideas can overlap, but they describe different roles.
For example, an AI recommendation can narrow running shoes to pairs under your budget. An agent can compare prices and stock across stores, then place an order if you allowed it.
AI commerce can improve traditional ecommerce without replacing a store or the shopper. A store still carries products, handles orders, and serves customers; AI may help people find what they need.
These AI vs. AI Commerce examples show why the terms matter. One use supports a human choice, while the other may complete several steps.
The same distinction applies to businesses. A system might draft a product description for review, while an agent could carry out an approved workflow across connected tools.
AI commerce does not have to alter the checkout or replace the online store. It can sit within familiar ecommerce processes and help with specific tasks.
With the terms in place, the next question is how AI assistance works in an ordinary online store.
How Does AI Commerce Work in an Online Store?
A returning shopper searching for a familiar product may see recommendations shaped by earlier visits or orders. Businesses can use AI in commerce today, starting with a bounded task and human review.
Past behavior is one kind of data a system can use, along with current searches, inventory, and sales patterns. The system looks for signals that help it make a prediction or suggestion.
For example, product recommendations may rank items that match a shopper’s interests or recent search. Search results can also move products with relevant descriptions and available stock higher on the page.
A business can use sales history and seasonal trends to forecast demand. A team member can review the forecast before ordering more products or changing a plan.
Some systems suggest pricing based on demand, stock, or market signals. An employee can set limits and approve changes, especially when a price shift could affect customer trust.
AI can flag a payment that looks like suspected fraud, or draft a customer support response. A person can review the alert or message before it affects a customer.
This cycle uses data, produces a result, and leaves a person to make the relevant decision. The human review point should match the risk of the task.
AI-driven commerce can fit into existing ecommerce workflows rather than replace them. A store might add search ranking first, then track whether shoppers find products more easily.
A small team could test a support draft for common delivery questions. It can compare response time and correction rates before using the tool more widely.
The assisted workflow keeps a person in charge of the outcome. A more autonomous agent can take on several connected steps, which changes how the work proceeds.
How Does Agentic Commerce Work?
A shopper delegates a purchase by stating a need, budget, and delivery preference. An agent can research and act only within the permissions you give it.
Agentic commerce combines autonomy, multi-step reasoning, and connections to other systems. The agent can work through a task, but its access and choices should have clear limits.
A shopping agent researches and purchases
You might ask a shopping agent to find running shoes for daily use under $120, available in your size, with free delivery. It can search more than one retailer and compare prices, stock, and delivery details.
The agent may apply eligible offers, then present a choice or complete checkout, depending on your instructions. If you set a maximum price and require approval, it should stop before spending more or placing an order.
Some commerce services have started to support agent-led transactions. ChatGPT Instant Checkout was live by late 2025, when ChatGPT had 900 million weekly users.
In early 2026, the Universal Commerce Protocol was released to help AI agents transact across retailers and payment systems using open standards. Such standards can make it easier for different systems to work together.
Adoption figures show interest, not universal use. In Europe, 38% of consumers used AI tools to compare options and decide faster, while 39% of German consumers were open to agents for online shopping.
One in four consumers across the UK, France, Germany, Italy, and Spain used AI tools to research and plan purchases. Worldwide, 78% of consumers wanted AI integrated into shopping.
Business agents act across connected systems
A business agent might review stock, suggest a price change, and start a supplier order through connected commerce tools. People can set approval steps based on the cost and impact of each action.
A standardized interface, often called MCP, can let an agent access systems and tools in a consistent way. Connections still need careful access rules, since an agent may touch orders, prices, and customer records.
A low-risk report may need less oversight than an order that commits money. The more an action affects customers or finances, the clearer its limits and review should be.
These early examples show how agents can handle a broader task than a recommendation. That shift can change where a brand competes when an agent selects a product.
What Changes When an AI Agent Chooses the Product?
Imagine two similar products, but only one has clear specifications, stock, and delivery details. An agent may favor the item it can understand and verify.
In AI commerce, brands can still shape human discovery through content, ads, search, and the shopping experience. Human discovery often includes browsing a category page, reading reviews, and comparing a brand’s product details.
Agentic commerce can move selection earlier, before a shopper visits a product page. An agent may scan product feeds and metadata to find an item that fits stated needs.
Human discovery versus algorithmic selection
A shopper may notice a familiar brand, read a product story, or respond to a useful ad. These moments help brands explain why a $90 running shoe differs from a cheaper pair.
An agent may instead compare the requested size, cushioning, price, stock, and delivery time. A product page’s design matters less if the agent makes its shortlist before the shopper sees that page.
This does not erase brand identity. Clear product details and a good customer experience can support both a person’s choice and an agent’s comparison.
Why machine-readable product information matters
Machine-readable product data uses consistent, structured attributes that software can interpret. A catalog might list shoe size, material, color, price, and stock in clear fields.
If one item lists sizes as “9” and another uses “US Men’s 9,” a system may struggle to compare them. Missing delivery times or unclear return terms can also make a product harder to assess.
Agents may read structured product feeds and metadata rather than interpret every page as a person would. Incomplete, inconsistent, or ambiguous details can leave an item out of consideration.
A brand should keep its product facts accurate across its own store and other sales channels. Machine readability complements brand identity; it does not automatically replace a helpful product page or customer experience.
These differences clarify why product information matters before an agent makes a choice. Businesses can also use AI for tasks that do not involve delegated purchasing.
What Can AI Do for Ecommerce Today?
An online store can help a shopper find an item and forecast whether it will be in stock. AI in retail and e-commerce can support customer tasks and behind-the-scenes work.
Useful tools depend on the task and the data it can access. These examples show where AI can help shoppers, store teams, or both.
- Personalized recommendations use product and customer data to suggest relevant items. Shoppers may find a matching accessory without searching the full catalog.
- Search ranking uses query details, product descriptions, and stock signals to order results. A shopper looking for waterproof boots should see relevant products first.
- Demand forecasting uses past sales and seasonality to estimate future needs. Merchandisers can use the estimate to plan stock before a busy period.
- Dynamic pricing uses demand, inventory, and pricing rules to suggest or change prices. A business needs clear limits to avoid confusing customers.
- Fraud detection checks order and payment patterns for signs of risk. Teams can review flagged orders rather than treating every alert as proof of fraud.
- AI-assisted customer support can draft replies using order details and approved policies. Support staff can edit the answer before sending it.
- Product descriptions and localized catalog content can be drafted for different products or markets. Staff should check product facts, tone, and translations.
These uses span customer-facing and operational work. A recommendation shapes what a shopper sees; a forecast helps a team decide what to stock.
AI for ecommerce: how it’s transforming the future is a practical question about repetitive work, not a promise of automatic growth. A tool may save time on first drafts, but staff still need to check the result.
The data also affects the answer. A forecast built on incomplete sales history may miss a seasonal pattern, while a stale inventory feed can recommend an unavailable item.
Businesses can start with a narrow task and record its current results. That gives a fair comparison of time saved, accuracy, or service quality.
The range of uses can be helpful, but activity alone does not prove value. The next step is to judge gains and limits with clear measures.
What Are the Benefits and Limits of AI in Ecommerce?
A revenue report or cost cut matters only when a business can link it to a defined AI task. Measure a change against a clear baseline, not a tool’s activity.
Useful measures connect results to business goals. The impact of artificial intelligence on e-commerce depends on what changed, how it was measured, and whether the gain lasts.
Where measurable gains can come from
A business can track incremental conversion or average order value after changing a recommendation or search process. It should compare similar periods and account for other changes that could affect sales.
Support costs and time to resolve common requests can show whether AI-assisted replies help. Content production time can show whether drafting tools speed up work without raising error rates.
A retailer survey found nearly 89% of surveyed retailers were using or exploring AI. Among respondents, 87% reported increased annual revenue after implementing AI, and 94% reported reduced operating costs.
Those figures are survey results, not a forecast for every business. A new tool may produce a different result, especially if the task or starting point differs.
The benefits of artificial intelligence in e-commerce are strongest when teams can tie a measurable gain to an actual business need. A faster process is useful when it keeps quality steady and frees time for work that needs judgment.
What AI cannot fix
AI cannot set a sound brand strategy or make a weak product fit customers better. It can speed up a poor decision just as readily as a good one.
Bad data can lead to wrong product matches, price suggestions, or stock forecasts. Unclear goals make it hard to tell whether an output helps the business.
Broken operations also limit results. A support system cannot resolve a delivery issue if order data is missing or the team has no clear way to fix it.
Can AI make money online? It can support a viable commerce business by helping with costs, sales, or service, but it does not guarantee earnings.
Set a baseline, track the same measure after a change, and check for unwanted effects on customers. Those checks also show where people remain responsible when AI makes work faster.
Is AI Taking Over Commerce Jobs?
A support system can draft an answer to a routine order question, while a person handles a dispute or sensitive case. AI is taking over or assisting with selected tasks, not commerce as a whole.
Repeatable work is easier to automate than decisions that depend on context, trust, or accountability. The change often affects parts of a job rather than removing every task in it.
Tasks AI can assist with
A tool can draft routine product copy from approved product facts. Staff can check that the text describes the right size, material, and use.
AI can sort common support requests or surface patterns for a merchandiser. A team member can then decide whether a rise in returns points to a product issue or unclear sizing.
These systems can reduce some repetitive steps, but they still need goals and limits. A draft should not become a promise about delivery or product performance without review.
Responsibilities that still need people
People set business goals and decide how the brand should speak to customers. They also handle exceptions, such as a delayed order tied to a customer’s urgent need.
Human judgment matters in sensitive cases, disputes, and situations where a standard reply could cause harm. Teams need people who can review whether a system follows policy and respects customer data.
Governance means setting rules for how a system can act and who checks its choices. Final accountability stays with the business, even when software suggests or completes a task.
No job is guaranteed to remain untouched by AI. Roles that combine judgment, relationships, strategy, and responsibility are less reducible to automated tasks.
A store employee may spend less time copying product details and more time resolving a customer’s unusual request. That shift still depends on good training and clear authority.
Distinguishing task automation from human accountability helps a brand prepare for agent-led shopping. The same distinction guides the data and transaction checks it should make.
How Can Brands Prepare for AI Shopping Agents?
A brand can check whether software can tell two similar products apart using catalog data alone. Clear product data helps systems compare items, but it cannot guarantee selection.
Start with the catalog, then test how an agent handles the path from discovery to a confirmed order. The checks should include customer permissions and the point where a person takes over.
Make the catalog machine-readable
Review each product’s structured attributes for completeness and consistency. A shoe listing should make its size, color, material, price, and stock easy to read.
Use the same names and units across similar items. If one shirt lists a chest size in inches and another uses a vague size label, a system may compare them poorly.
Keep pricing and inventory current across connected platforms. Out-of-date stock can lead an agent to recommend an item that a shopper cannot buy.
Test discovery and checkout
Review how AI answer engines describe your brand and products. Check whether they identify key features correctly and distinguish your item from a similar one.
Test whether an agent-initiated basket can become a confirmed order. Make sure the path respects consent, payment rules, and customer-service handoffs.
Use a short set of checks during a catalog and checkout review:
- Attribute completeness for each product type.
- Consistent product names and units.
- Current availability, pricing, and stock signals.
- Clear return and delivery details.
- Reliable order confirmation and support handoff.
A machine-readable catalog does not guarantee that an agent will select a product. It gives systems clearer facts to assess, while price, fit, availability, and shopper instructions still affect the choice.
Testing also helps a brand spot errors before they affect a real order. Once the data and transaction path are clear, the team can match tools to specific tasks.
Which AI Tools Fit Different Ecommerce Tasks?
A small team writing catalog copy needs different tools from one managing recommendations or customer messages. The best fit depends on data access, integration, controls, and the work to improve.
Start with the task, not a claim that one product suits every store. General tools can help create or summarize content, while platform tools may connect more closely to store workflows.
General tools for content and customer communication
ChatGPT, Claude, and Gemini can help draft product descriptions, summarize customer feedback, or create first versions of routine messages. Copy.ai and Jasper also support marketing and catalog writing.
People should check every draft for product accuracy and brand fit. A fluent description can still get a shoe’s materials, dimensions, or care instructions wrong.
Ecommerce and platform-native tools
Platform features may work with store data or merchant tasks. Shopify Magic can assist with product descriptions; Sidekick, in the Shopify admin, can analyze sales trends, generate reports, and offer basic customer segmentation insights.
Adobe Commerce uses Adobe Sensei for commerce AI capabilities. It can connect commerce data with Adobe Experience Cloud tools for analytics, customer data, and campaigns.
Other tools focus on particular parts of the customer experience. Choose by workflow and integration, not by the number of features on a product page.
- Customer conversations: Tidio, Manychat, and SleekFlow.
- Recommendations and merchandising: Rebuy and LimeSpot.
- Visual content edits: Canva Magic Edit.
- Drafts and summaries: ChatGPT, Claude, Gemini, Copy.ai, and Jasper.
Using AI for ecommerce can start with one narrow workflow, such as drafting descriptions for a single product category. Keep a person in the review step and track corrections as well as time saved.
Check how each tool handles customer and product data, and whether it fits existing platforms. A useful tool should support the process without weakening consent, accuracy, or brand voice.
Choosing a tool does not decide how much authority it should have. A contained feature and an agentic system call for different levels of access and oversight.
When Should a Business Choose AI or Agentic Commerce?
A business with frequent, connected procurement choices has a stronger case for a controlled agent pilot than a store with a simple catalog. Choose autonomy only when the task needs it and the controls can contain its risks.
Fit the system to the business problem, the quality of its data, and the cost of a mistake. A targeted AI feature may solve a smaller problem with less change to daily work.
Use these checks to compare a focused AI task with an agentic commerce pilot:
- Repair fragmented data before adding autonomy.
- Prioritize forecasting or pricing when margin pressure is the main problem.
- Use productivity tools when a small team needs to reduce repeat work.
- Test controlled agents when decisions are frequent and complex.
- Require evidence of incremental profit, not just clicks or tool use.
Agentic commerce may suit B2B procurement, travel booking, or marketplaces with changing supply. Those settings can involve many linked decisions that people repeat often.
A mid-sized apparel or cosmetics brand may face more risk from autonomous merchandising than from targeted AI. A wrong price or product choice can conflict with brand rules or create compliance and service problems.
For that business, a tool that helps staff compare trends may be safer than one that changes the full catalog. Stronger autonomy also requires clear oversight, consistent rules, and reliable systems.
Measure results through gross margin, customer lifetime value, customer acquisition cost efficiency, and operating costs. A rise in clicks does not prove an investment improved profit or customer value.
Set a limit on what the system can change, who approves exceptions, and how staff can stop it. A pilot should track both the intended gain and errors or customer complaints.
The right level of autonomy depends on the business problem and its controls. Choose one measurable task, set limits, and test whether the result improves a real business outcome.
Conclusion
The useful choice is not whether to adopt every new AI feature, but which task needs improvement. Targeted AI supports a human-led workflow, while agentic commerce delegates connected actions and needs stronger data, integration, and oversight.
For a practical next step, choose one repetitive task and record its current results. Test a limited AI workflow against that baseline before expanding its access or autonomy.
How to Audit, Consolidate, and Choose Tools that Actually Work Together: Building a Modern MarTech Stack
The average enterprise pays for over 100 software applications, yet employees actively use only a fraction. This digital bloat drains your budget and productivity. When systems do not connect, teams face disconnected data, inconsistent reports, and endless manual workarounds.
Building a Modern MarTech Stack is not about adding more tools to your arsenal. It means creating a connected system that drives real business results. To succeed, move beyond simple purchasing and use a strict, finance-led evaluation process.
This guide offers a practical framework for auditing your current environment and consolidating overlapping capabilities. We will show you how to test new alternatives and apply strict governance.
By focusing on data readiness and workflow fit, you can turn a fragmented setup into a streamlined growth engine. Stop paying for complexity and start investing in efficiency.
What the Case Study Reveals About MarTech Stack Fragmentation
When a marketing team grows faster than its processes, technical debt can overwhelm even talented professionals. Many organizations buy software for urgent problems without considering its long-term effect on their technology ecosystem.
Meet the Marketing Team Behind the Stack Audit
A mid-sized software firm scaled its operations quickly over three years. Its marketing team grew from five people to thirty, and each hire preferred different software platforms. Without a central governance strategy, the team soon built a bloated set of disconnected applications.
Leaders eventually saw that rapid expansion had created a fragmented environment. They paid for several subscriptions with nearly identical functions but could not create one accurate customer acquisition cost report.
How Duplicate Tools Created Cost, Data, and Workflow Problems
The audit found a chaotic mix of overlapping subscriptions. The team used three email marketing platforms, two separate CRM instances, and four analytics tools. This redundancy caused inflated operational costs and major data silos.
Because the systems did not communicate, the team could not track a lead from the first click through the final sale. Staff spent hours moving CSV files between systems to match basic performance metrics. This work reduced productivity and caused frequent reporting errors.
Why More Modern Marketing Technology Did Not Automatically Improve Results
The firm first believed that modern marketing technology would fix its efficiency problems. Instead, new tools exposed and worsened its process gaps. Advanced software without an integration plan created more places for data to disappear.
Better results require more than the latest features. The team must judge each piece of modern marketing technology by its role, integration abilities, and measurable value. Without accountability and clean data flows, costly platforms will not provide the expected return on investment.
Building a Modern MarTech Stack Around Business Outcomes
Your technology stack should link your company’s financial goals with daily marketing work. A strong martech strategy starts with clear business results, not software features or vendor promises. These results might include higher customer lifetime value or a shorter sales cycle.
Translate Revenue Goals Into Marketing Technology Requirements
To build a strong stack, translate revenue goals into clear technical needs. If you want better pipeline quality, your martech strategy must prioritize lead scoring and data enrichment tools. Each software choice should support your quarterly targets.
Do not buy tools based on polished sales demonstrations. Clean metric definitions and usable source data matter more than a long list of bells and whistles. Each tool must fix a specific bottleneck blocking your team from reaching revenue milestones.
Connect Customer Journeys to the Marketing Technology Stack
Modern marketing requires a clear view of customer interactions across many channels. Your technology should move data smoothly from the first touchpoint to the final conversion. When systems are disconnected, you cannot provide a personalized experience.
Map each customer lifecycle stage to find where your tools succeed or fail. If a customer moves from an email campaign to your website, the transition should feel invisible and preserve useful data. Integration is the backbone of a successful customer journey, giving your team one view of every prospect.
Set Success Measures for Efficiency, Data Quality, and Campaign Performance
Clear success measures help maintain a healthy stack over time. Set benchmarks for efficiency, data completeness, and campaign performance early in planning. These metrics show whether your martech strategy delivers the expected return on investment.
Focus on attribution confidence and reliable reporting. If data is fragmented or inconsistent, your team cannot make informed decisions. Strict data quality standards keep your technology useful instead of creating operational friction.
How to Inventory Every Tool, Integration, and Owner
You cannot manage what you cannot see, so a thorough inventory supports success for your marketing technology stack. Many organizations face hidden costs and security risks because they lack a clear view of their software ecosystem. Documenting every asset helps you make informed decisions about your digital infrastructure.
Capture Core Platforms, Point Solutions, and Shadow IT
A complete inventory must cover more than the enterprise systems managed by your IT department. You also need to uncover shadow IT, including unauthorized extensions, spreadsheets, and niche tools bought with company cards. These hidden solutions often duplicate functions and create major data silos.
Start by surveying team leads to identify every application used in daily workflows. Capture sanctioned platforms and the smaller point solutions teams depend on. This comprehensive approach ensures that no tool stays hidden during your audit.
Document Each Tool’s Users, Purpose, Cost, and Contract Terms
After listing the tools, record the details that define each tool’s value. For every entry, document its main business purpose, active users, and contract terms. Also track renewal dates and total subscription costs to avoid unexpected budget spikes.
Assign an accountable owner to every tool in your marketing technology stack. This person manages access, monitors usage, and keeps the tool aligned with business goals. Clear ownership prevents the “orphan software” problem, which can drain budgets after its original purpose ends.
Map Data Flows Between Salesforce, HubSpot, Google Analytics 4, and Other Systems
The final step is visualizing how your systems communicate. Map data flows between core platforms such as Salesforce, HubSpot, and Google Analytics 4. Understanding these movements is essential for maintaining data integrity and security.
Use data lineage and role-based access controls to check that your integrations work reliably. Documenting these connections helps you find where data may become stuck or corrupted. A well-mapped marketing technology stack helps your team trust insights from reporting tools.
How to Audit Adoption, Redundancy, and Technical Fit
Unused features and duplicate platform abilities often hide costs. By optimizing martech tools, organizations can recover budget and simplify daily work. A thorough audit examines how your team uses each tool in its current stack.
Measure Whether Teams Use the Features They Pay For
Review login frequency and feature reports first. Many platforms show which modules staff never use. If your team pays for advanced automation but schedules basic emails, you may overspend on unnecessary complexity.
Compare assigned licenses with active user lists. This check prevents payments for departed employees or inactive accounts. Optimizing martech tools means matching subscription tiers to your marketing department’s needs.
When usage is low, consider downgrading or combining service plans.
Find Overlapping Capabilities Across Email, CRM, Analytics, and Automation Tools
Redundancy often enters a stack when departments buy separate solutions. Your CRM may include email features that duplicate a standalone email service provider. This overlap fragments data and makes teams manage several logins for one task.
Review workflow records for manual data transfers between overlapping systems. Optimizing martech tools means finding these bottlenecks and selecting one source of truth for customer data. Fewer platforms can improve team efficiency and data consistency.
Separate Genuine Platform Gaps From Training and Process Gaps
Not every performance problem comes from a faulty tool. Sometimes, teams lack training and cannot use a platform well. Before replacing a system, interview power users about their daily frustrations.
If software has the needed capability, focus on better documentation and hands-on workshops. If it lacks essential integrations or cannot scale, you have found a genuine technical gap. Separating these cases is vital for optimizing martech tools and supporting long-term growth.
Evaluating Data Quality and Integration Readiness
Before adopting new platforms, verify that data moves smoothly across your entire ecosystem. A truly integrated marketing technology stack needs more than software; it needs clean, reliable data flow. Without it, your team risks operational failure and fragmented customer insights.
Test Identity Resolution, Consent, and Field Consistency
Successful data management starts with accurate identity resolution. Ensure one customer profile stays consistent across your CRM, email platform, and analytics tools. Standardizing field naming conventions prevents duplicate records and synchronization errors.
Also, verify that consent status travels with each user record. If a customer opts out in one system, that preference must spread instantly. This consistency defines high-performing integrated marketing technology.
Trace Lead, Account, and Customer Data Across the Stack
To validate your architecture, trace records from capture through the full customer lifecycle. Follow a lead from a landing page into your CRM and then into your reporting dashboard. This process reveals hidden gaps in account hierarchies and data mapping.
Testing these paths shows where data may be lost or corrupted. Reliable data tracking ensures accurate, actionable marketing attribution. It also confirms that your sales team receives the right context for every account.
Assess Integration Reliability, Latency, and Error Handling
Even the best tools fail when their connections are unstable. Measure latency between systems to ensure your automation triggers fire in real-time. High latency often causes missed opportunities and poor customer experiences.
Also, evaluate how systems respond when an integration breaks. A robust integrated marketing technology setup includes automated alerts and recovery protocols. These features protect workflows from unexpected downtime and data loss.
Protect Governance, Privacy, and Regulatory Requirements
Treat data security and compliance as design requirements, not afterthoughts. Ensure your stack follows regional privacy laws and internal data residency policies. Auditability is critical for maintaining trust with customers and stakeholders.
Use strict permissions to control who can access or change sensitive customer information. By prioritizing governance, you build a secure environment that supports long-term growth. This proactive approach reduces risk while maximizing the value of your technology investments.
Creating a Consolidation Business Case
Many organizations struggle to identify the best martech solutions because they favor popular vendors over operational needs. A sustainable stack requires tools that fit your business model, not just attractive features. A strong business case gives stakeholders and leaders evidence for needed changes.
Rank Tools by Strategic Value, Business Risk, and Switching Difficulty
Start by scoring your current inventory on three critical dimensions. Strategic value measures how directly a tool supports revenue growth and customer retention. Assess business risk, including data security vulnerabilities, compliance gaps, and vendor stability.
Finally, assess the switching difficulty of each platform. Estimate the time, technical effort, and possible downtime needed to move data or retrain staff. Tools deeply embedded in workflows but offering low strategic value are prime consolidation candidates.
Calculate Total Cost Beyond Subscription Pricing
The true price of a tool often hides beyond the monthly invoice. When seeking the best martech solutions, calculate the Total Cost of Ownership (TCO). This includes hidden costs such as implementation fees, ongoing integration maintenance, and specialized training.
Include administrative overhead and security monitoring costs. A tool needing extensive manual data cleaning or custom coding costs far more than its sticker price. These factors keep financial projections accurate and defensible.
Choose What to Retain, Replace, Merge, or Retire
After gathering your data, categorize every tool: Retain platforms that offer high value and low risk. replace platforms that no longer meet your technical requirements. You may merge overlapping functions into one, more powerful system.
If a tool offers little utility or adds needless complexity, it is time to retire it. This framework helps you present a logical, evidence-based strategy to your team. These categories keep your stack lean, efficient, and aligned with long-term goals.
Using a MarTech Strategy Scorecard to Compare Platforms
A formal scorecard turns subjective opinions into objective data, supporting better decisions. By avoiding gut feelings, teams keep their mar tech platform selection aligned with long-term business goals. This process helps stakeholders see trade-offs and explain investments to leaders.
Define Weighted Criteria for Mar Tech Platform Selection
Begin by weighting categories according to their impact on your organization. Prioritize factors like integration capabilities, data governance, and security over secondary features. Scoring each vendor against these criteria creates a clear needs hierarchy for the final decision.
For example, security and compliance deserve the highest weight in a highly regulated industry. This choice helps each tool meet your internal control environment requirements. Prioritizing these technical requirements early prevents choosing a platform that looks great but cannot integrate with existing infrastructure.
Compare Total Value Rather Than Feature Counts
Many teams choose software because it offers the most advertised features. Yet dozens of unused functions can create needless complexity and bloat. Focus instead on the actual workflow fit and the platform’s ability to solve specific business problems.
Assess total value by considering ease of use and implementation speed. An intuitive platform can increase adoption, which helps deliver a positive return on investment. True value lies in efficiency, not in the number of dashboard buttons or menus.
Involve Marketing, Sales, IT, Finance, and Legal in the Decision
A strong mar tech platform selection needs input from several departments to avoid blind spots. Marketing and Sales must confirm customer-journey support, while IT reviews the technical architecture. Finance and Procurement check contract terms against budget cycles, while Legal handles privacy and risk assessments.
Early stakeholder involvement builds support and reveals roadblocks before they become costly issues. This collaboration makes the final choice more than a marketing tool: it becomes a secure and scalable asset for everyone.
Testing the Best MarTech Solutions Before Making a Commitment
Buying new software takes more than a polished sales pitch. It requires careful testing through a structured pilot program. Testing beyond vendor demos shows whether the best martech solutions work in your business environment.
Build a Proof of Concept Around a Real Customer Journey
To judge a platform, map it to a real customer journey. Use a lead from your actual sales funnel instead of generic test data. This test shows how the software handles your business logic and complex data requirements.
Test Lead Capture, Segmentation, Automation, Reporting, and Handoffs
Your pilot should follow a lead from capture to the final sales handoff. Check that consent management stays intact at every stage. Test Automation triggers for speed and accuracy, and audit reporting dashboards for actionable insights, not just vanity metrics.
Evaluate Vendor Support, Documentation, and Implementation Partners
Technical capability is only one part of choosing the best martech solutions. Assess the vendor’s support response and the clarity of its technical documents. If you use third-party implementation partners, check whether they can connect the tool to your current infrastructure without unnecessary downtime.
Set Clear Pass-Fail Criteria for the Pilot
Before the pilot starts, define clear success measures that all stakeholders approve. If the platform misses these benchmarks, reject it or require fixes before making a long-term commitment. These strict pass-fail criteria reduce the risks of poor adoption and wasted budget.
Planning Mar Tech Implementation Without Disrupting Campaigns
A successful mar tech implementation adds new systems without stopping active marketing campaigns. It modernizes your infrastructure while keeping leads and customer engagement moving. This steady flow supports business growth.
Sequence Migration by Data Dependencies and Business Risk
Do not replace every tool in your stack at once. Prioritize migration by system data links and the revenue risk of failure.
Map dependencies among your CRM, marketing automation, and analytics platforms. By sequencing your rollout, you reduce the risk of breaking data pipelines that support your sales team.
Protect Active Campaigns, Reporting Continuity, and Historical Records
Data integrity is essential during a transition. Keep historical records accessible, and keep reporting dashboards accurate throughout the mar tech implementation process.
Avoid starting over if it would erase valuable performance data. Instead, connect legacy systems with new platforms for a seamless transition during ongoing marketing efforts.
Assign Ownership for Configuration, Migration, Testing, and Approval
Clear accountability helps prevent mistakes that cause project delays. Assign an owner to each migration phase, including configuration and final system validation.
Set formal approval checkpoints for marketing, IT, and sales stakeholders. They must approve the new setup. This structured approach meets each department’s needs.
Train Teams Before the New Workflow Becomes Mandatory
Technology works only when people can use it well. Prioritize training that shows how new tools improve daily tasks, not only technical features.
Introduce the workflows before they become mandatory. This gives your team time to share feedback and adjust to the new environment. This proactive mar tech implementation strategy reduces resistance and helps your team hit the ground running on day one.
Measuring the Results of the Consolidated Stack
A clear measurement plan helps prove the value of a streamlined stack. By tracking key KPIs, you can show how your martech stack consolidation improves business results. This data tells a clear story about efficiency and growth.
Compare Pre- and Post-Consolidation Operating Costs
The clearest success signal is a lower total cost of ownership. Compare old software subscription fees with the new, leaner budget. Do not forget hidden costs, such as implementation overhead and maintenance hours.
Eliminating duplicate licenses and similar features can create Significant savings. Track these savings to show stakeholders a clear return on investment. They also create a baseline for future budget planning.
Track Campaign Speed, Data Completeness, and Workflow Reliability
Better marketing technology stack performance shows through greater efficiency. Measure the time needed to launch a campaign, from ideas to execution. Many teams cut launch times by 50% or more after consolidation removes manual data entry.
Check data completeness and synchronization error rates across your core platforms. A reliable stack should reduce broken integrations and data silos. Workflow reliability gives your team more time for creative strategy and less time troubleshooting.
Measure Improvements in Lead Management and Customer Experience
Your stack should serve customers, so track lead velocity and journey mapping. For example, cutting a three-week lead close time to under one week shows strong progress. Consistent data flow supports more personal interactions at every touchpoint.
Study how your consolidated tools affect the customer experience. When systems connect well, you can deliver useful content at the right time. Better lead management is directly linked to higher conversion rates and stronger revenue outcomes.
Use Quarterly Reviews to Prevent New Tool Sprawl
Even a well-optimized stack can develop “feature creep” without regular checks. Hold quarterly reviews to decide whether new tools are needed or existing platforms can meet the need. This approach prevents fragmented systems from returning.
Use these reviews to check user adoption and find features that teams underuse. Governance is a continuous process requiring attention from marketing and IT leaders. Close monitoring keeps your technology a strategic asset, not a growing liability.
Lessons From the Case Study for Long-Term Stack Governance
Establishing robust martech governance stops redundant tools and fragmented data from growing over time. After you consolidate the stack, disciplined oversight protects those gains. This keeps your organization from returning to uncontrolled tool growth and data chaos.
Make Tool Requests Follow a Consistent Evaluation Process
Every new software request must pass through a standard review process. The process should assess the business need, data access, and integration effects. A formal review of costs, security, and legal compliance gives each addition a clear strategic purpose.
Assign ownership before signing any contract. This limits shadow IT and keeps someone accountable for the tool’s performance and eventual retirement.
Maintain a Living Architecture Map and Data Dictionary
A static document cannot keep pace with modern marketing needs. Maintain a living architecture map to show how systems connect and share information. The map gives your entire team one trusted source of truth.
Pair it with a comprehensive data dictionary, so everyone defines metrics like “lead” or “customer” the same way. This shared meaning protects data integrity as customer journeys change.
Balance Flexibility With Standards for Integrated Marketing Technology
Effective marketing technology governance does not block innovation. It lets teams test ideas safely within clear guardrails. You should encourage approved platforms while limiting unvetted point solutions.
Clear standards for integration and data security support agility without weakening system stability. This balance helps maintain a high-performing, integrated ecosystem.
Define When the Stack Should Expand, Consolidate, or Be Rebuilt
Your stack is a changing asset that needs active lifecycle management. Define triggers for when to expand, consolidate, or rebuild your setup. Triggers may include a specific revenue milestone, a business strategy shift, or lower system performance.
Review these triggers often to prevent technical debt from building. Treating your stack as a living entity keeps technology a competitive advantage, not a burden.
Conclusion
Success in the digital landscape takes more than buying the latest software. Building a Modern MarTech Stack depends on matching your tools with clear business outcomes, not chasing feature lists.
Prioritize disciplined audits and reliable data so your systems work together. Adding more platforms rarely improves results when internal governance and team adoption remain weak.
Test real customer journeys to confirm that your setup works. Compare your investments’ total value with your campaigns’ actual performance. Protect data quality and maintain operational control to keep your infrastructure agile.
Building a Modern MarTech Stack requires an ongoing commitment to efficiency and clarity. Keep your architecture flexible for growth while maintaining structure for accountability. Review integrated systems regularly to prevent tool sprawl and keep marketing operations running at peak performance.
Intrattenimento digitale: domande frequenti sull’esperienza nei casinò online
Luna is betting you’re tired of fitness subscriptions and offering its screenless band as the solution
ECB warns banks of new AI risks
The Netherlands just blocked a US company from buying the cloud provider that runs Dutch digital identity
Dropbox founder Drew Houston steps down as CEO after 19 years as the company he built gets squeezed by Google and Apple
Apple opens its post-Quantum encryption vault
Smart glasses are back, and this time they’re pretending to be normal
Starlink Mini may finally cut the cord with a battery-powered dish
Best Premium Business Laptops for Professionals in 2026
My Experience Using eSIM Plus in Turkey: Is It Worth Switching to eSIM?
Notte in luce: l’intrattenimento dei casinò online raccontato
Călătorie vizuală prin cazinourile online: atmosferă, culoare și detaliu
Midnight Tabs: A Smooth Tour Through Online Casino Entertainment
Only 3.3 per cent of users pay for Copilot, so Microsoft is finally making it optional